† Research mentorship
Selected Publications
Domain
Paradigm
VoiceDesigner: Text-to-Voice Generation and Editing via Unified Diffusion Modeling and Data Augmentation
arXiv, 2026
[TL;DR] [Paper] [Homepage] [BibTeX]
A unified diffusion framework for diverse, controllable text-to-voice generation and voice editing.
VoiceDesigner: Text-to-Voice Generation and Editing via Unified Diffusion Modeling and Data Augmentation
arXiv, 2026
[TL;DR] [Paper] [Homepage] [BibTeX]
A unified diffusion framework for diverse, controllable text-to-voice generation and voice editing.
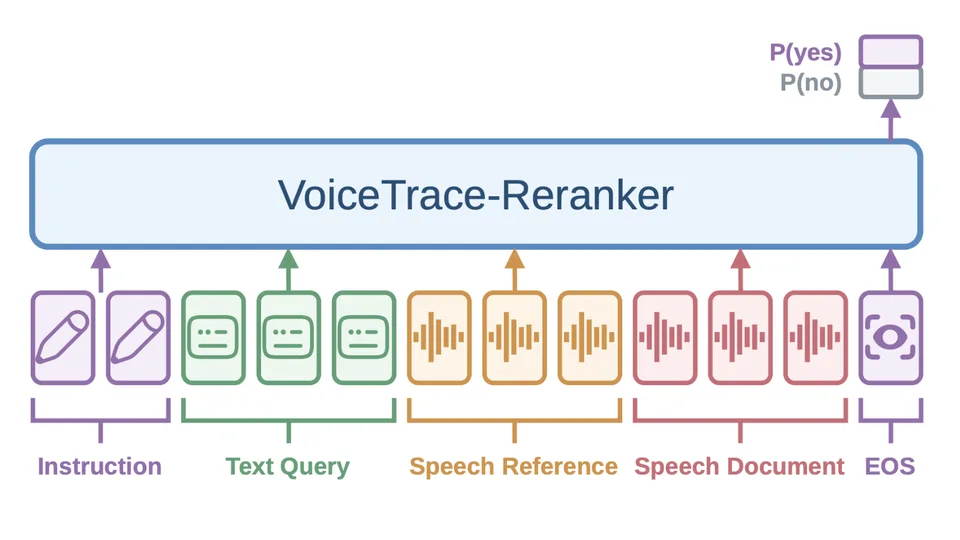
VoiceTrace: A Benchmark and Retrieval Framework for Who-Said-What Speech Retrieval
arXiv, 2026
[TL;DR] [Paper] [Homepage] [Benchmark] [BibTeX]
A benchmark and two-stage retrieval framework that jointly retrieves spoken content by what was said and who said it.
VoiceTrace: A Benchmark and Retrieval Framework for Who-Said-What Speech Retrieval
arXiv, 2026
[TL;DR] [Paper] [Homepage] [Benchmark] [BibTeX]
A benchmark and two-stage retrieval framework that jointly retrieves spoken content by what was said and who said it.
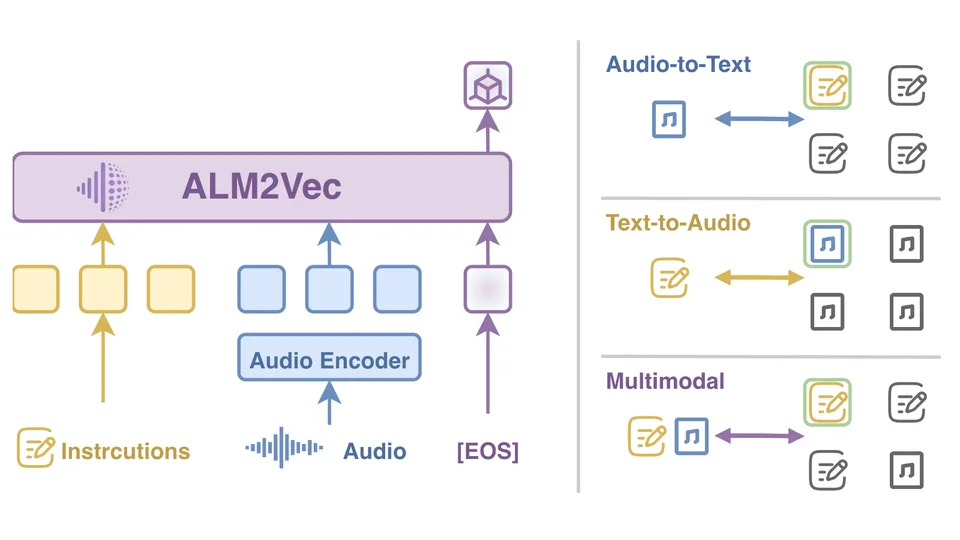
ALM2Vec: Learning Audio Embeddings for Universal Audio Retrieval with Large Audio-Language Models
arXiv, 2026
[TL;DR] [Paper] [Homepage] [BibTeX]
A universal audio embedding framework that transfers large audio–language models into an instruction-aware retrieval space across domains and tasks.
ALM2Vec: Learning Audio Embeddings for Universal Audio Retrieval with Large Audio-Language Models
arXiv, 2026
[TL;DR] [Paper] [Homepage] [BibTeX]
A universal audio embedding framework that transfers large audio–language models into an instruction-aware retrieval space across domains and tasks.
CapSpeech: Enabling Downstream Applications in Style-Captioned Text-to-Speech
TASLP, 2026
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
A style-captioned TTS dataset and framework enabling controllable, style-aware text-to-speech for downstream applications.
CapSpeech: Enabling Downstream Applications in Style-Captioned Text-to-Speech
TASLP, 2026
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
A style-captioned TTS dataset and framework enabling controllable, style-aware text-to-speech for downstream applications.
Summary of The Inaugural Music Source Restoration Challenge
ICASSP, 2026 Challenge
[TL;DR] [Paper] [Homepage] [BibTeX]
A summary of the inaugural Music Source Restoration Challenge, covering tasks, data, baselines, and key findings.
Summary of The Inaugural Music Source Restoration Challenge
ICASSP, 2026 Challenge
[TL;DR] [Paper] [Homepage] [BibTeX]
A summary of the inaugural Music Source Restoration Challenge, covering tasks, data, baselines, and key findings.
SoloSpeech: Enhancing Intelligibility and Quality in Target Speech Extraction Through a Cascaded Generative Pipeline
TASLP, 2026
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
A cascaded generative pipeline for target speech extraction that improves intelligibility and perceptual quality.
SoloSpeech: Enhancing Intelligibility and Quality in Target Speech Extraction Through a Cascaded Generative Pipeline
TASLP, 2026
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
A cascaded generative pipeline for target speech extraction that improves intelligibility and perceptual quality.
FlexSED: Towards Open-Vocabulary Sound Event Detection
WASPAA, 2025 Spotlight
[TL;DR] [Paper] [Code] [Live Demo] [BibTeX]
An open-vocabulary sound event detection approach that generalizes to unseen classes via flexible text-conditioned modeling.
FlexSED: Towards Open-Vocabulary Sound Event Detection
WASPAA, 2025 Spotlight
[TL;DR] [Paper] [Code] [Live Demo] [BibTeX]
An open-vocabulary sound event detection approach that generalizes to unseen classes via flexible text-conditioned modeling.
EzAudio: Enhancing Text-to-Audio Generation with Efficient Diffusion Transformer
Interspeech, 2025 Oral
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
An efficient diffusion transformer that improves text-to-audio generation quality while reducing compute.
EzAudio: Enhancing Text-to-Audio Generation with Efficient Diffusion Transformer
Interspeech, 2025 Oral
[TL;DR] [Paper] [Homepage] [Live Demo] [BibTeX]
An efficient diffusion transformer that improves text-to-audio generation quality while reducing compute.
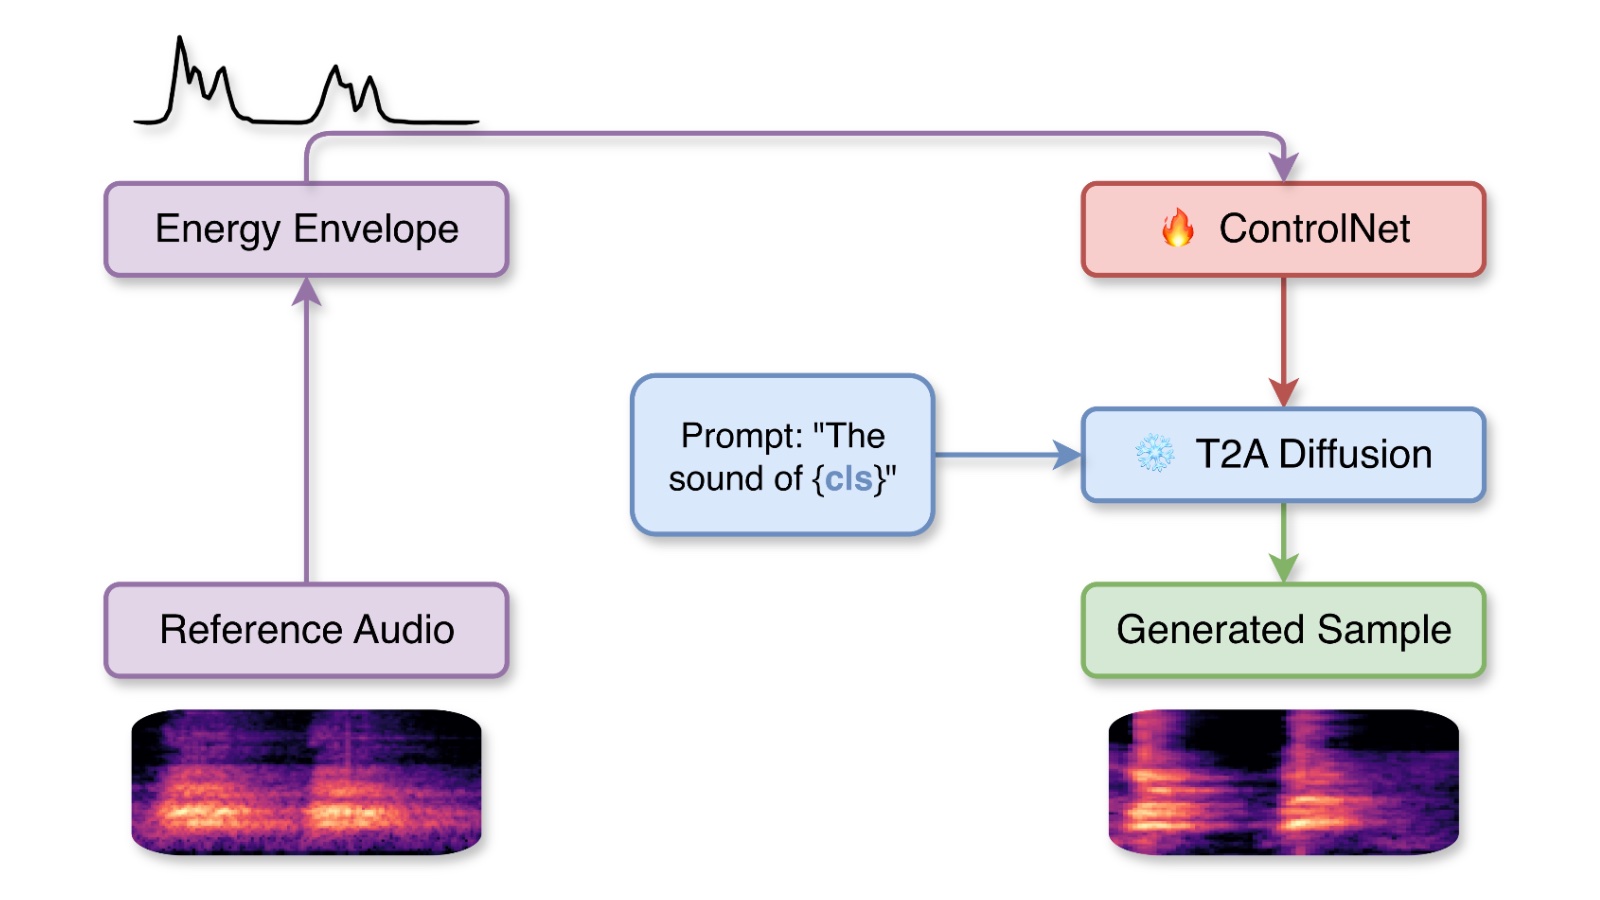
SynSonic: Augmenting Sound Event Detection through Text-to-Audio Diffusion ControlNet and Effective Sample Filtering
WASPAA, 2025
[TL;DR] [Paper] [Live Demo] [BibTeX]
A text-to-audio diffusion ControlNet augmentation pipeline with sample filtering to improve sound event detection.
SynSonic: Augmenting Sound Event Detection through Text-to-Audio Diffusion ControlNet and Effective Sample Filtering
WASPAA, 2025
[TL;DR] [Paper] [Live Demo] [BibTeX]
A text-to-audio diffusion ControlNet augmentation pipeline with sample filtering to improve sound event detection.
SoloAudio: Target Sound Extraction with Language-Oriented Audio Diffusion Transformer
ICASSP, 2025
[TL;DR] [Paper] [Homepage] [BibTeX]
A language-conditioned audio diffusion transformer for target sound extraction from mixtures.
SoloAudio: Target Sound Extraction with Language-Oriented Audio Diffusion Transformer
ICASSP, 2025
[TL;DR] [Paper] [Homepage] [BibTeX]
A language-conditioned audio diffusion transformer for target sound extraction from mixtures.
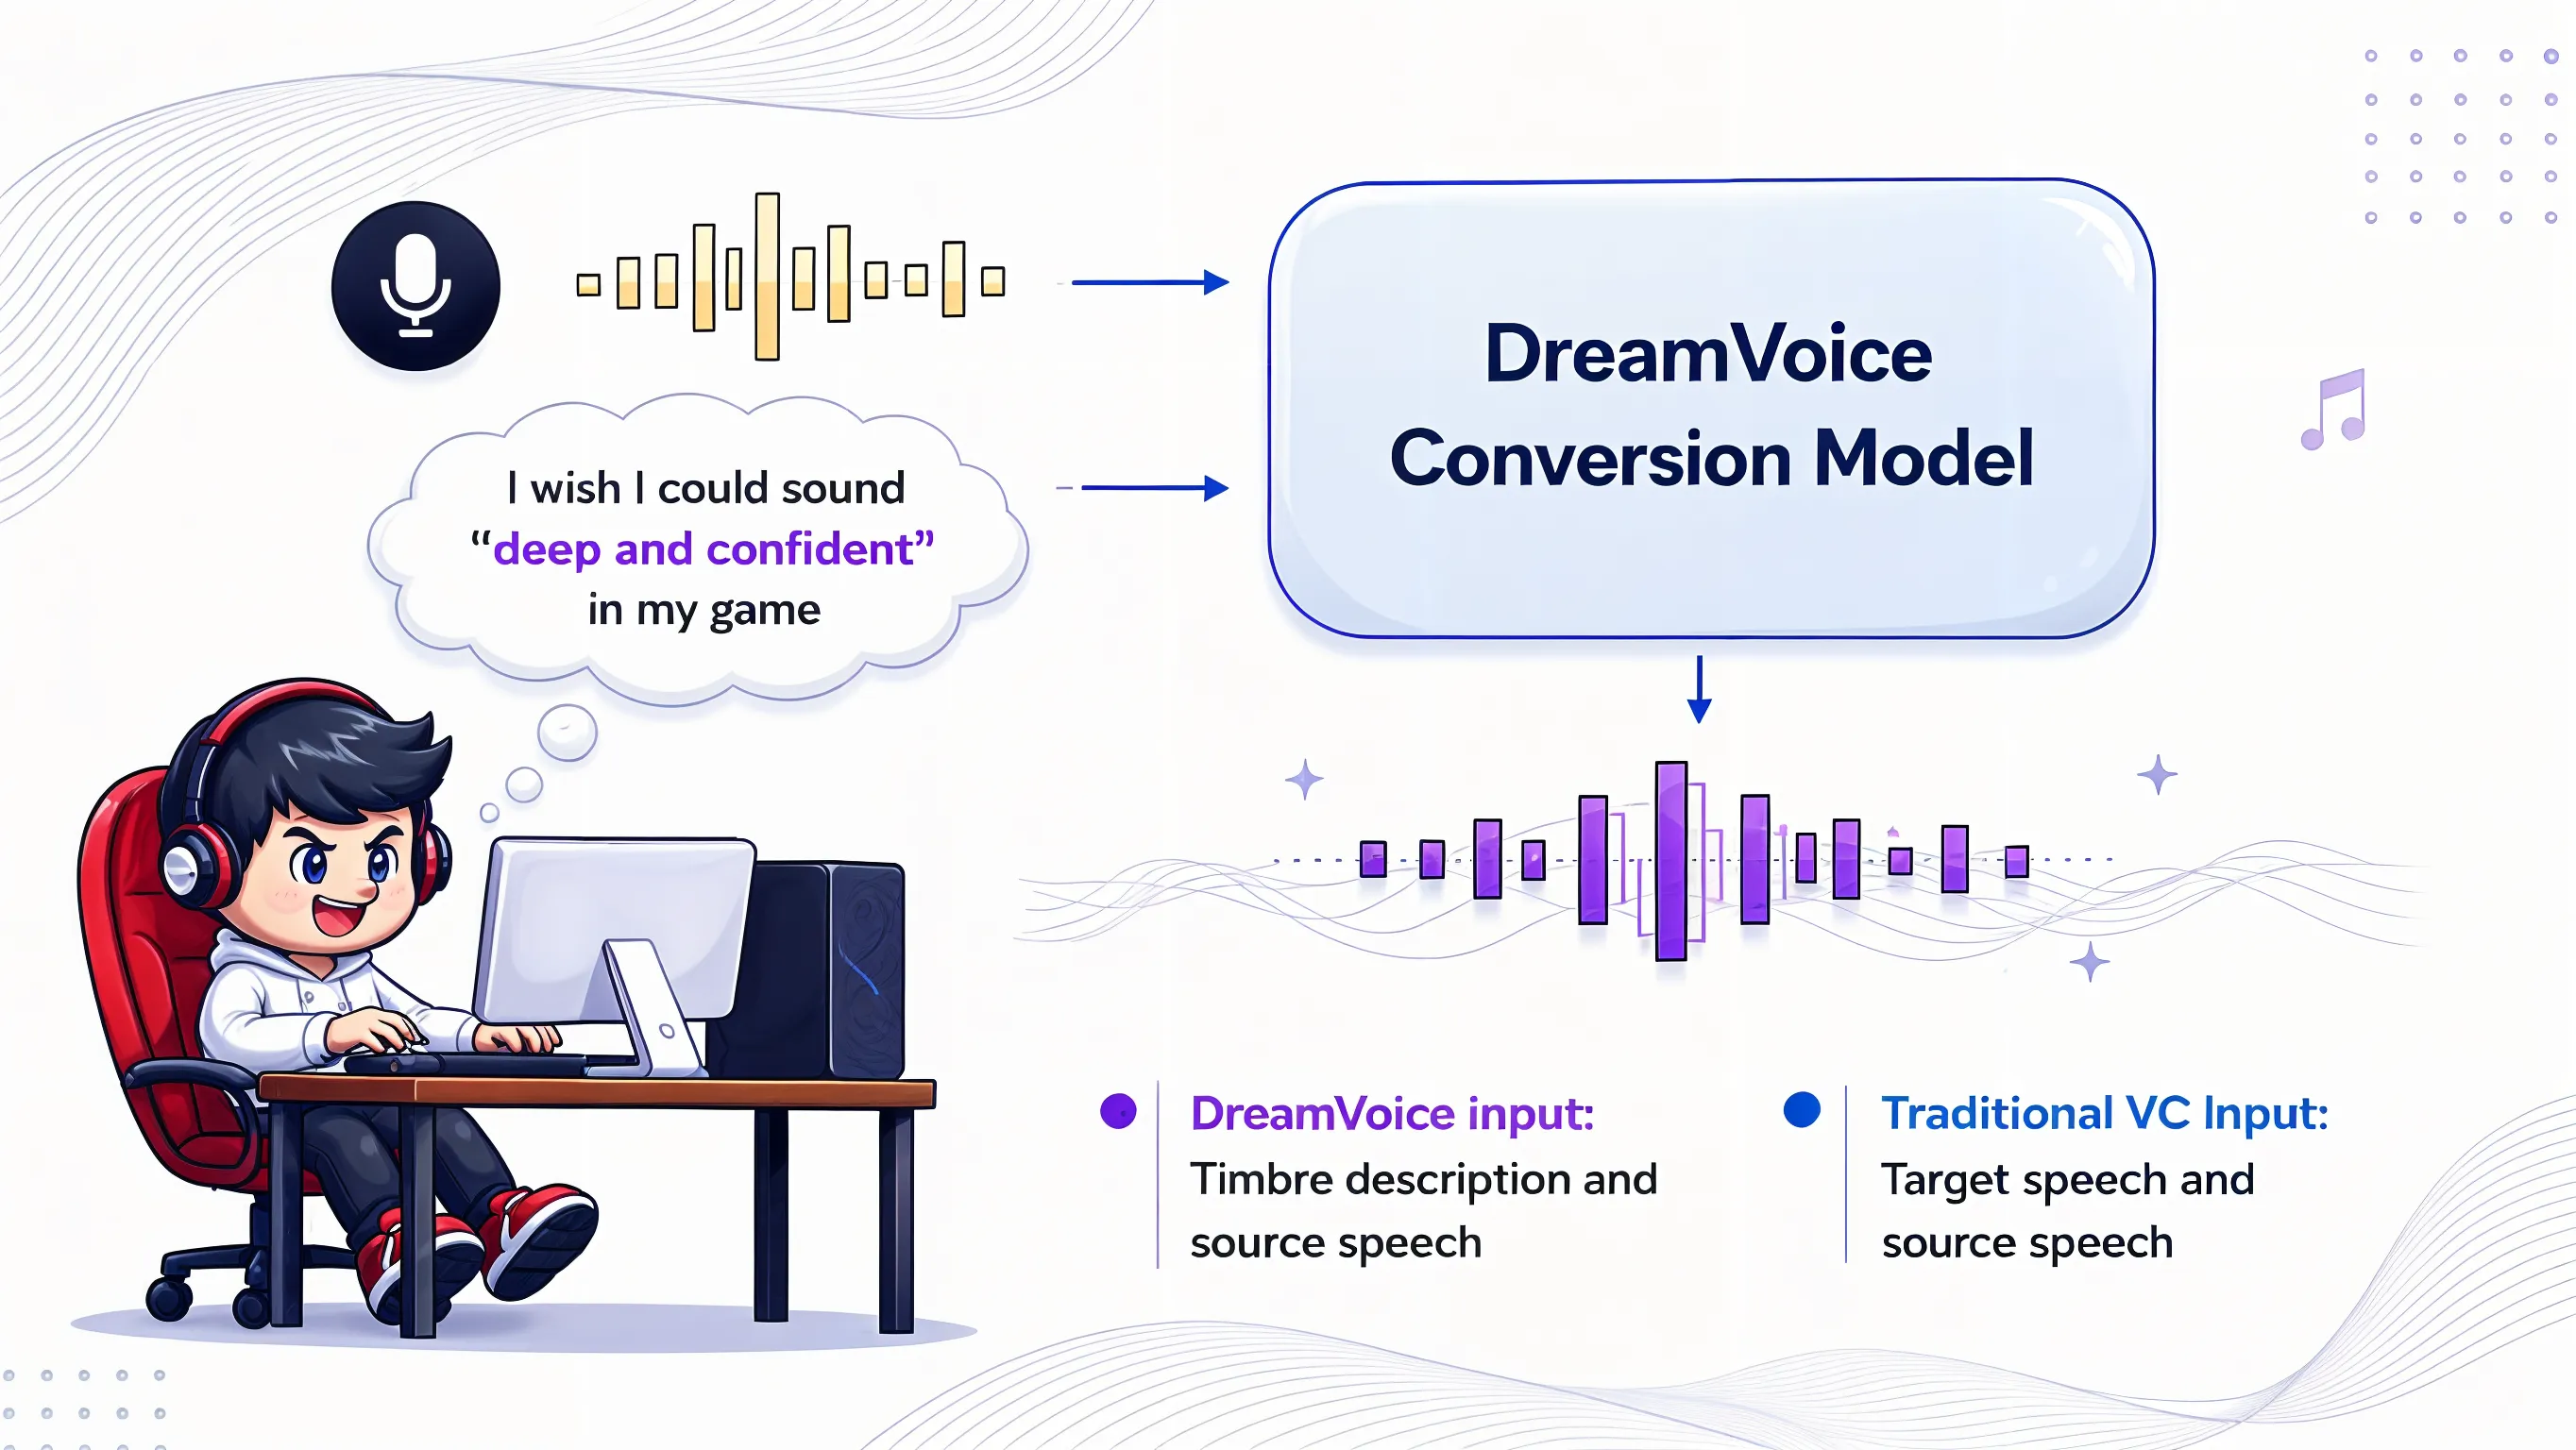
DreamVoice: Text-Guided Voice Conversion
Interspeech, 2024
[TL;DR] [Paper] [Homepage] [BibTeX]
Text-guided voice conversion that follows natural-language prompts to control voice attributes and speaking style.
DreamVoice: Text-Guided Voice Conversion
Interspeech, 2024
[TL;DR] [Paper] [Homepage] [BibTeX]
Text-guided voice conversion that follows natural-language prompts to control voice attributes and speaking style.
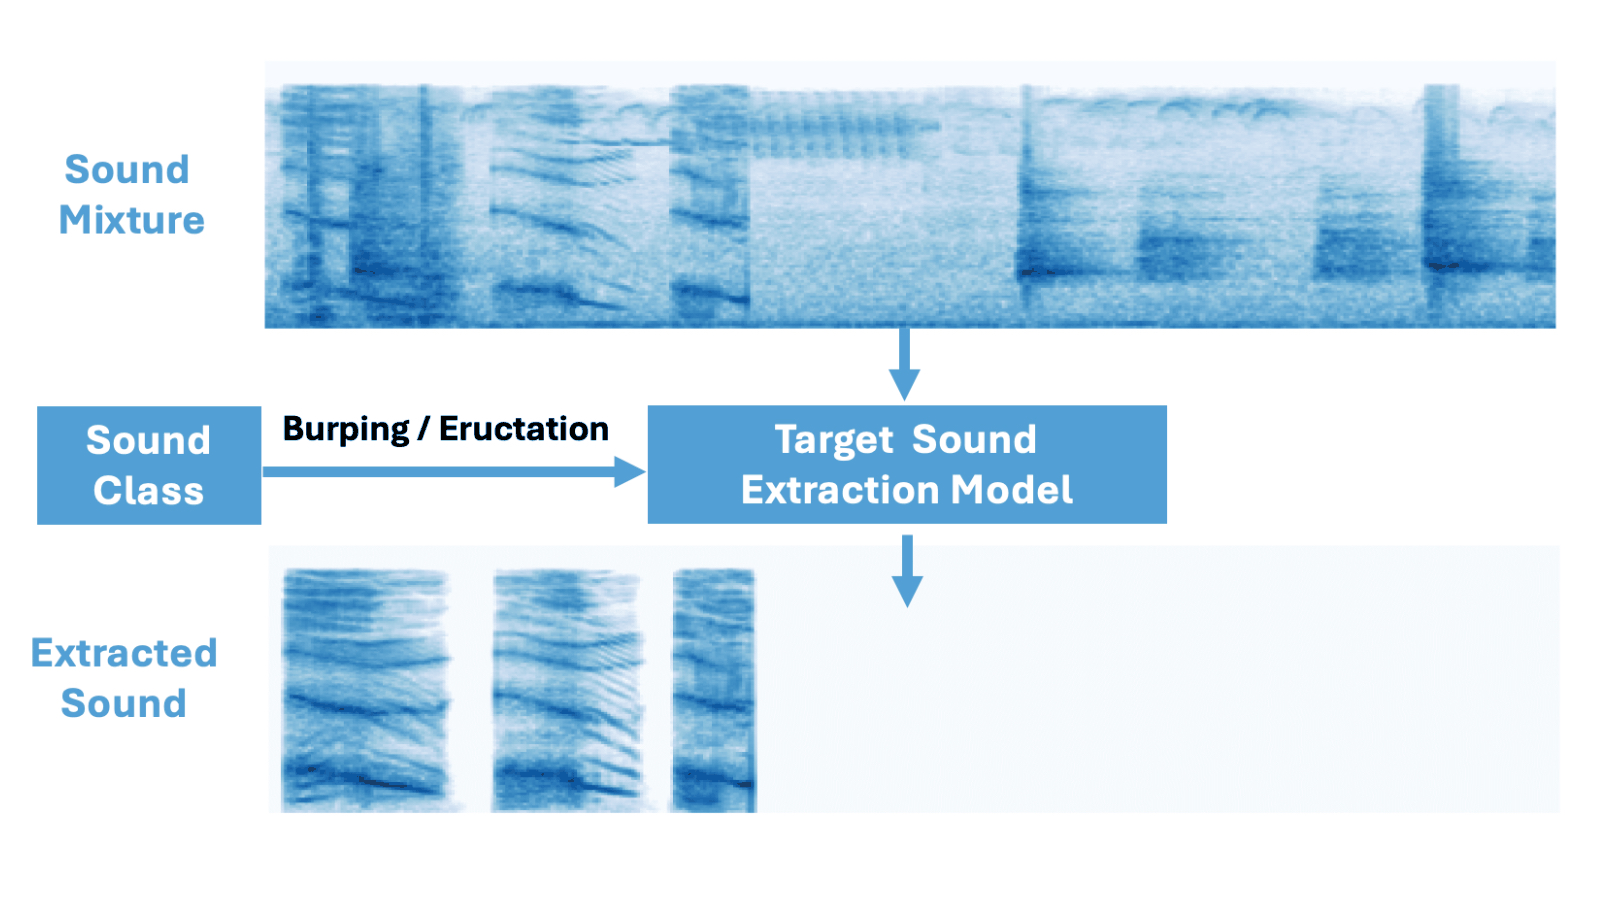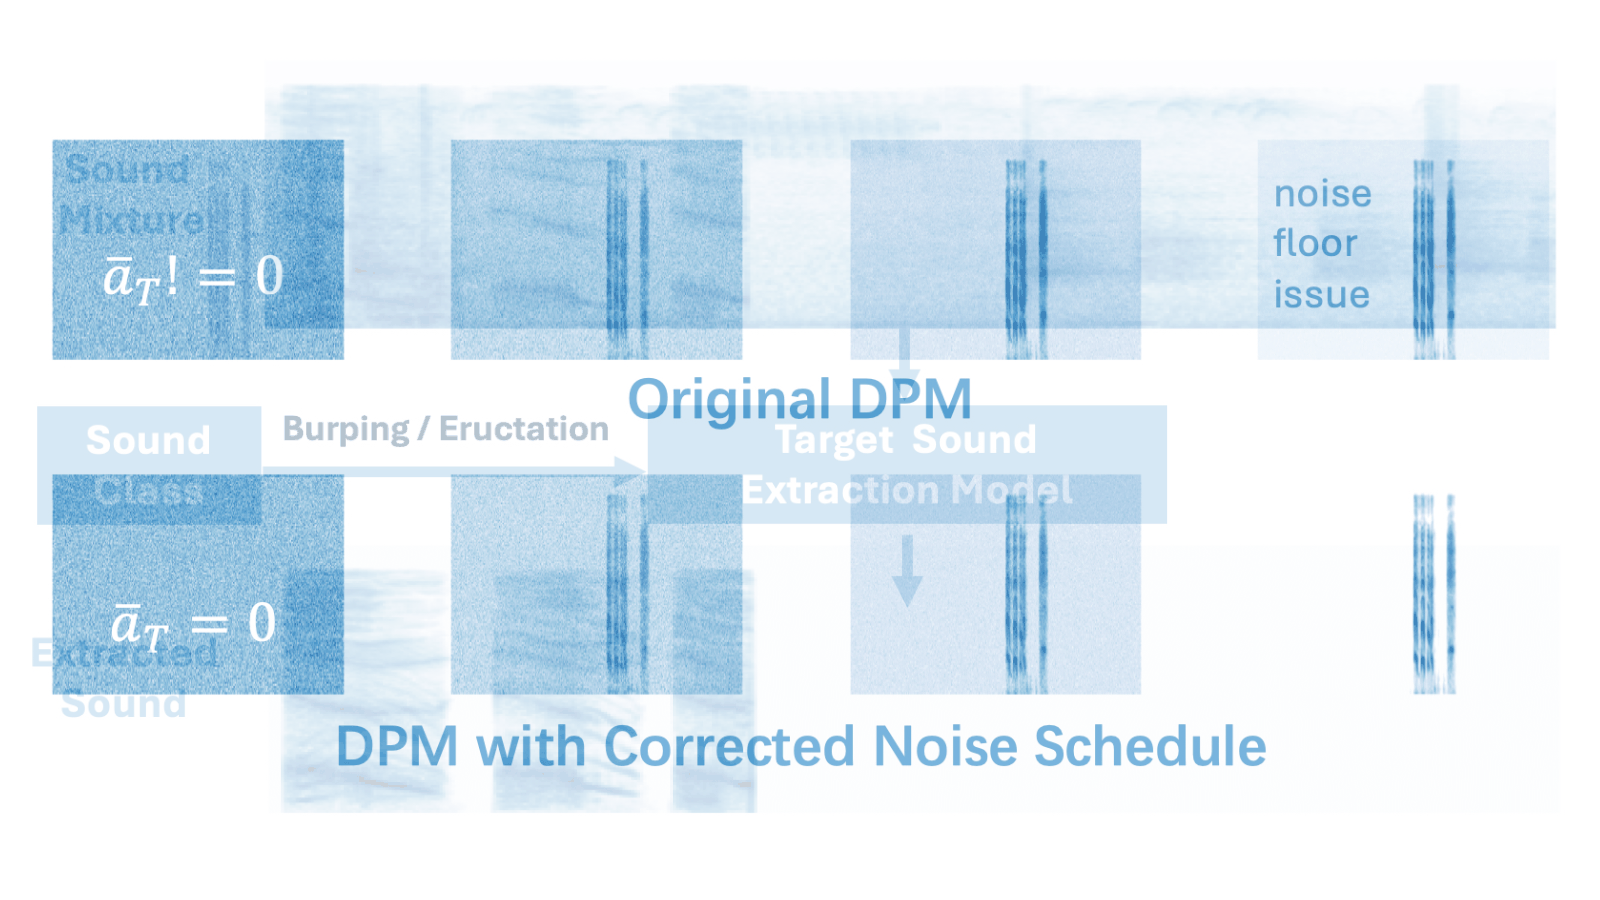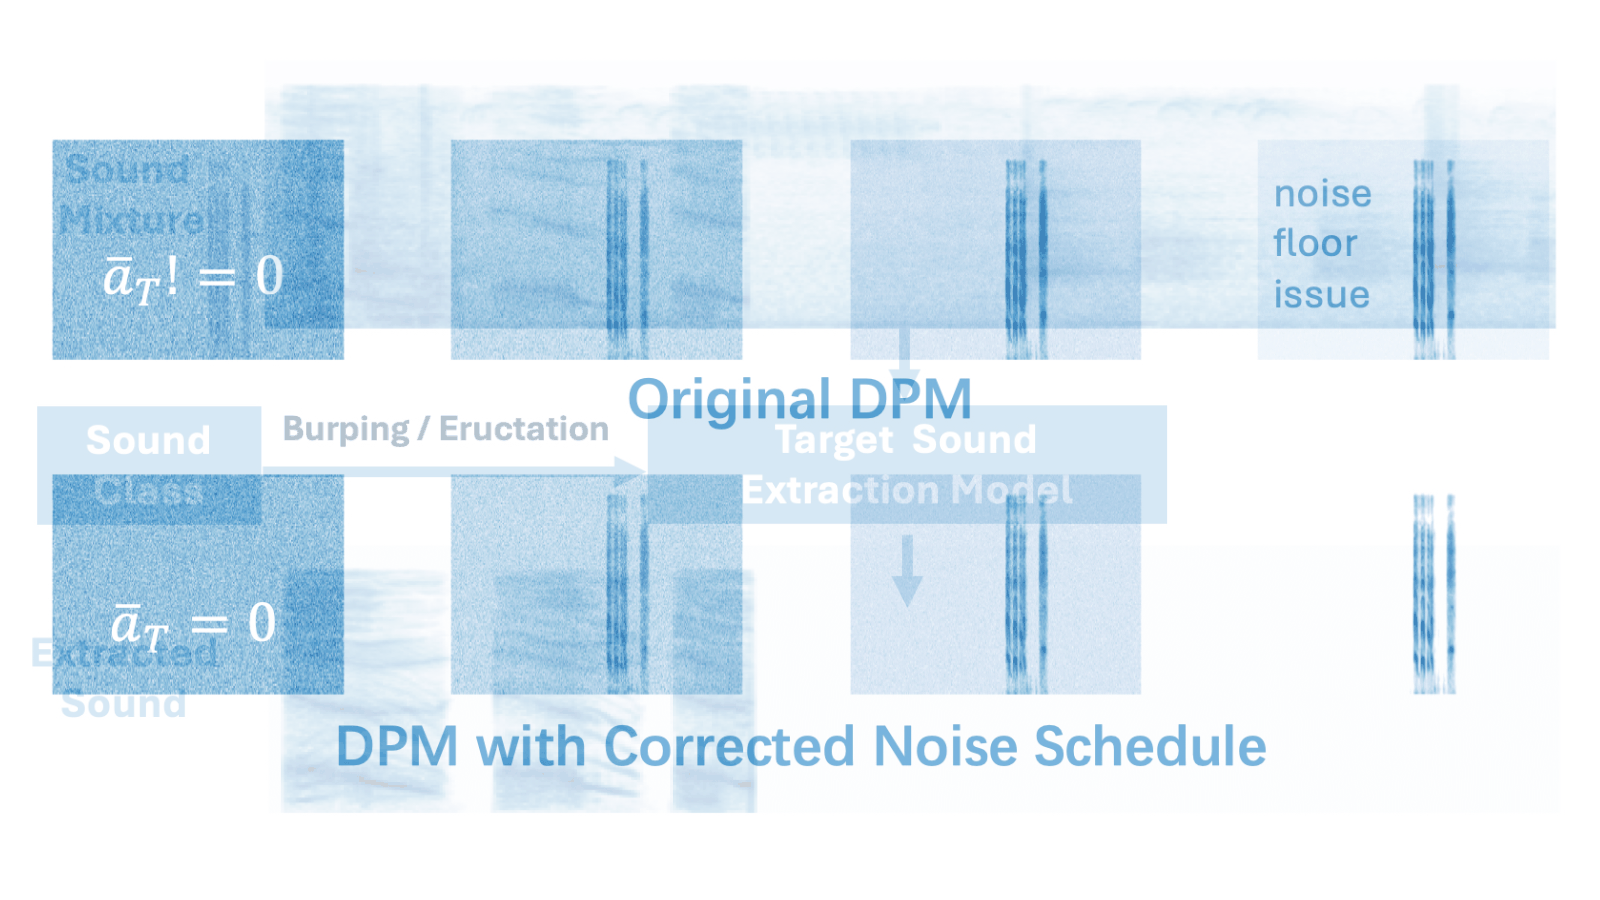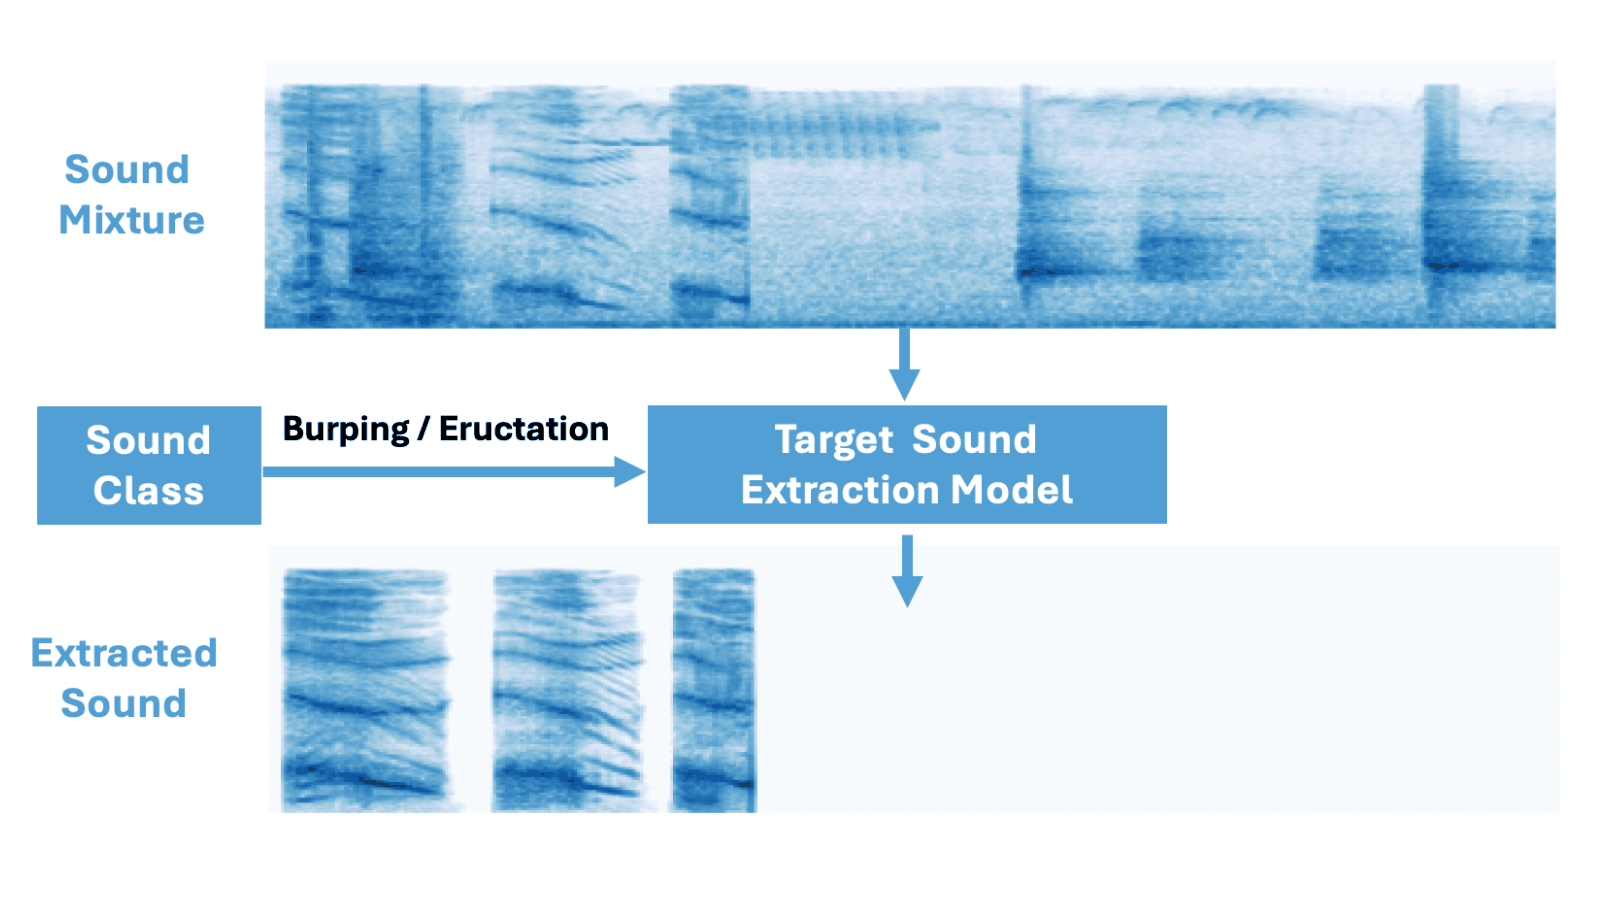
DPM-TSE: A Diffusion Probabilistic Model for Target Sound Extraction
ICASSP, 2024
[TL;DR] [Paper] [Homepage] [BibTeX]
A diffusion probabilistic model for target sound extraction that separates a desired source from audio mixtures.
DPM-TSE: A Diffusion Probabilistic Model for Target Sound Extraction
ICASSP, 2024
[TL;DR] [Paper] [Homepage] [BibTeX]
A diffusion probabilistic model for target sound extraction that separates a desired source from audio mixtures.

Diff-Pitcher: Diffusion-based Singing Voice Pitch Correction
WASPAA, 2023 Oral
[TL;DR] [Paper] [Homepage] [BibTeX]
A diffusion-based method for singing voice pitch correction that adjusts pitch while preserving timbre and expression.
Diff-Pitcher: Diffusion-based Singing Voice Pitch Correction
WASPAA, 2023 Oral
[TL;DR] [Paper] [Homepage] [BibTeX]
A diffusion-based method for singing voice pitch correction that adjusts pitch while preserving timbre and expression.